Credit decisions live in the exceptions
The policy manual describes the standard borrower. The house's real credit judgment lives in exceptions, overrides and committee precedent that are recorded but never structured, which is why AI credit tools can read the file and still cannot decide.
Download the PDFEvery commercial lender has a credit policy. Almost none of them lend to it. The manual describes the borrower the bank would like to have: a leverage ceiling, a coverage floor, a maturity cap. The borrowers who arrive have an add-back the policy did not anticipate, a sponsor the committee has backed three times before, and a covenant the house always waives once and never twice. The decision is made in the gap between the manual and the case, and that gap is where the institution's credit judgment lives.
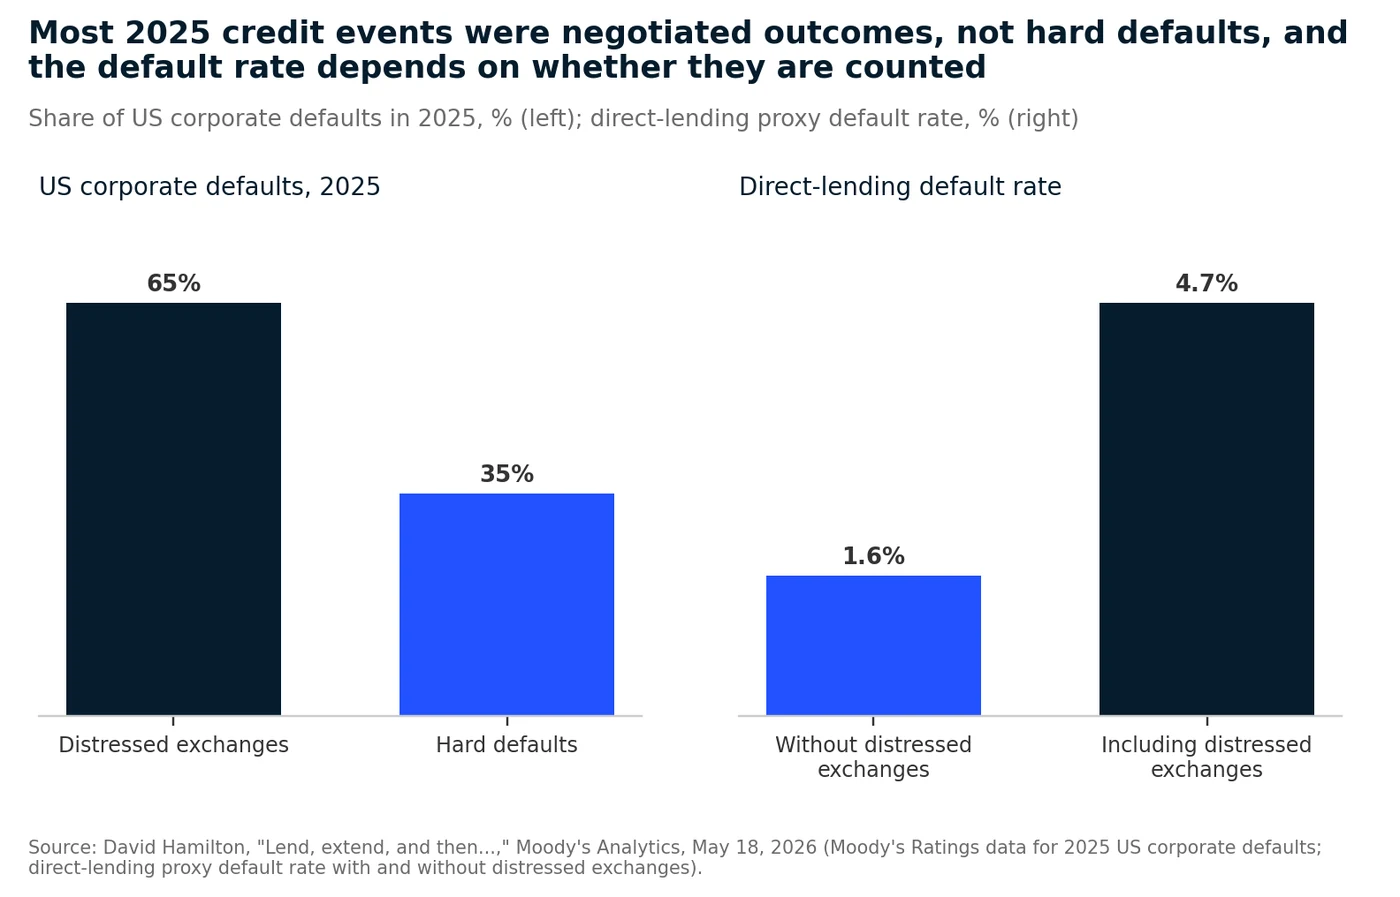
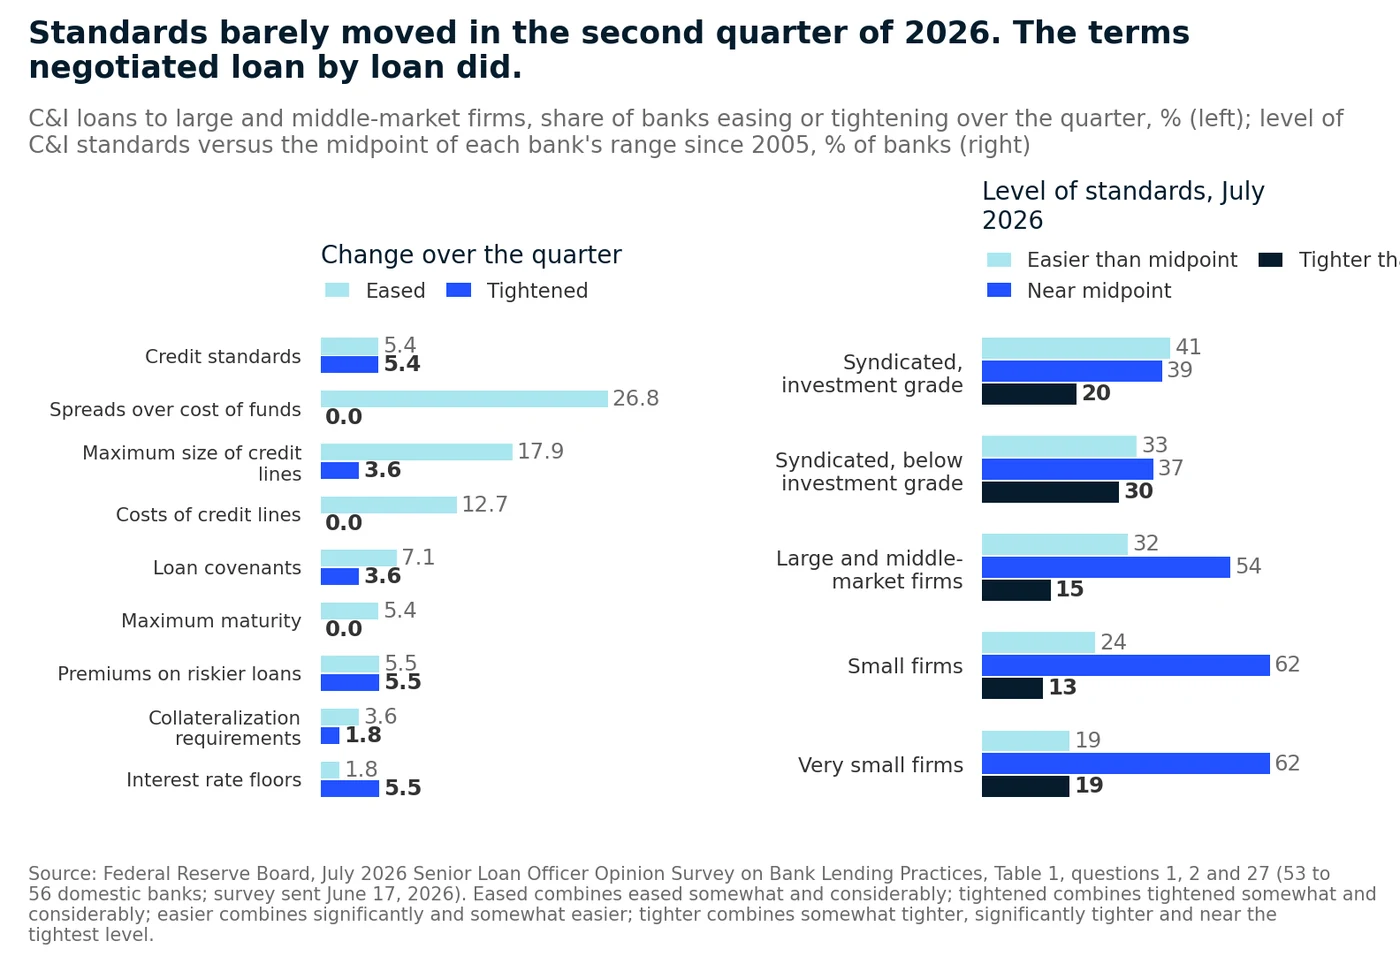
The 2026 numbers show how much of the credit outcome is now decided in that gap rather than in the model. Moody's reports that 65 percent of all US corporate defaults in 2025 were distressed exchanges rather than hard defaults, and that a direct-lending default rate of 1.6 percent becomes 4.7 percent once those negotiated outcomes are counted (Exhibit 1).1 The IMF's April stability report found that selective defaults in direct lending, which include amend-and-extend and payment-in-kind options, had stabilized while payment defaults kept rising from a low base.2 In the Federal Reserve's July survey of senior loan officers, 89.3 percent of banks left their standards for large and middle-market commercial loans unchanged in the quarter, yet 26.8 percent narrowed spreads, 17.9 percent raised the maximum size of credit lines, and 7.1 percent eased covenants.3 The standard did not move. The terms, negotiated loan by loan, did.
Banks are deploying AI in credit into this setting. In the Cambridge Centre for Alternative Finance's 2026 global survey, credit risk and underwriting is among the most widely adopted uses, cited by 54 percent of firms, while 79 percent of regulators rate explainability as critical or important and 55 percent of industry respondents name loss of human oversight as a top risk.4 Among US banks under $100 billion in assets, 72 percent have implemented generative AI and 49 percent of those use it in lending; 30 percent have implemented agentic AI, and 17 percent of those use it in lending.5 The tools are in the credit function. What they are not allowed to do is decide. Our argument is that the reason is not model capability. It is that the exception logic, committee precedent and override conventions that make up a house's credit judgment have been recorded for decades but never structured, and a system cannot apply what the institution has never made explicit.
The standard case is no longer the standard case
The policy manual assumes a distribution of borrowers that the market has stopped producing. The BIS's September analysis of US direct lending found that the share of technology borrowers with negative EBITDA rose from 23 percent before 2020 to 46 percent after it, that median debt to EBITDA among profitable borrowers roughly tripled, and that the interquartile range of spreads narrowed from 3.25 percentage points to 1.75. The authors conclude that "spreads on direct loans may no longer fully account for borrower fundamentals."6 The FSB's May report put the private credit market at $1.5 trillion to $2.0 trillion at the end of 2024, "untested in a prolonged economic downturn," with payment-in-kind usage rising.7
Banks are inside this market, not beside it. Jamie Dimon's April letter to shareholders records that nonbanks' share of leveraged lending rose from 54 percent in 2010 to 64 percent in 2025, and that global private credit assets grew from $0.3 trillion to $1.8 trillion over the same period.8 The FDIC's second-quarter profile shows bank loans to nondepository financial institutions up $279.1 billion, or 22.4 percent, over twelve months, the fastest-growing category on the industry's balance sheet.9 In the 2025 Shared National Credit review, published in January, nonbank "other investors" held 21.5 percent of the $6.9 trillion in syndicated commitments but 60.7 percent of the $592.9 billion that was special mention or classified.10
None of this means credit is deteriorating in the aggregate. The FDIC's noncurrent rate on C&I loans was 0.96 percent in the second quarter, and past-due and nonaccrual C&I balances fell 11 basis points to 1.27 percent.9 The OCC's spring risk perspective describes credit quality as satisfactory while noting that payment-in-kind arrangements and restructurings in private credit may be masking deterioration.11 The point is narrower. The borrowers in the pipeline no longer resemble the borrower in the policy, so every file is to some degree an exception, and the quality of the book depends on how well the house applies its exception logic, not its standard.
Where the credit judgment actually lives
Ask a chief credit officer where the bank's judgment is written down and the answer is usually the policy. Ask which decisions of the last year they are proudest of and the answer is always an exception: the refinancing approved above the leverage ceiling because of the sponsor's record of equity support, the covenant reset granted because the house has learned that the first miss in that industry is cyclical and the second is structural. The reasons are specific, repeatable and shared among a few senior people. They are recorded in minutes, approval chains, exception logs and the memo's mitigants paragraph. They are not structured anywhere.
The same is true of the reserve overlays. Under CECL, the qualitative factors management layers onto the modeled loss estimate "may carry a material share of the reserve," and when the OCC revised its Allowances for Credit Losses booklet in July the examiner guidance became explicit: the magnitude and the direction of each factor need a documented reason, and the most common finding is "policy that doesn't match practice."12 The revised model risk guidance, SR 26-2, now requires that conceptual soundness cover "qualitative judgments" and names, among the things documentation should support, "the tracking of recommendations, responses, and exceptions."13 Supervisors are asking for the exception layer in writing. Most institutions can produce it only by interview.
Moody's history of soft credit events shows why the exception layer is the one that matters economically. Across 1,173 borrowers since 1979, roughly two thirds of those that went through a distressed exchange did not go on to a hard default, about one in four did, and over 70 percent of eventual hard defaults came within two years.1 Whether to lend, extend or exit at the first negotiated outcome is a precedent decision, and the lender who remembers what the house did last time is making a call the policy cannot describe. That memory is the asset. No current AI deployment can reach it.
The models can read the file. They cannot read the house.
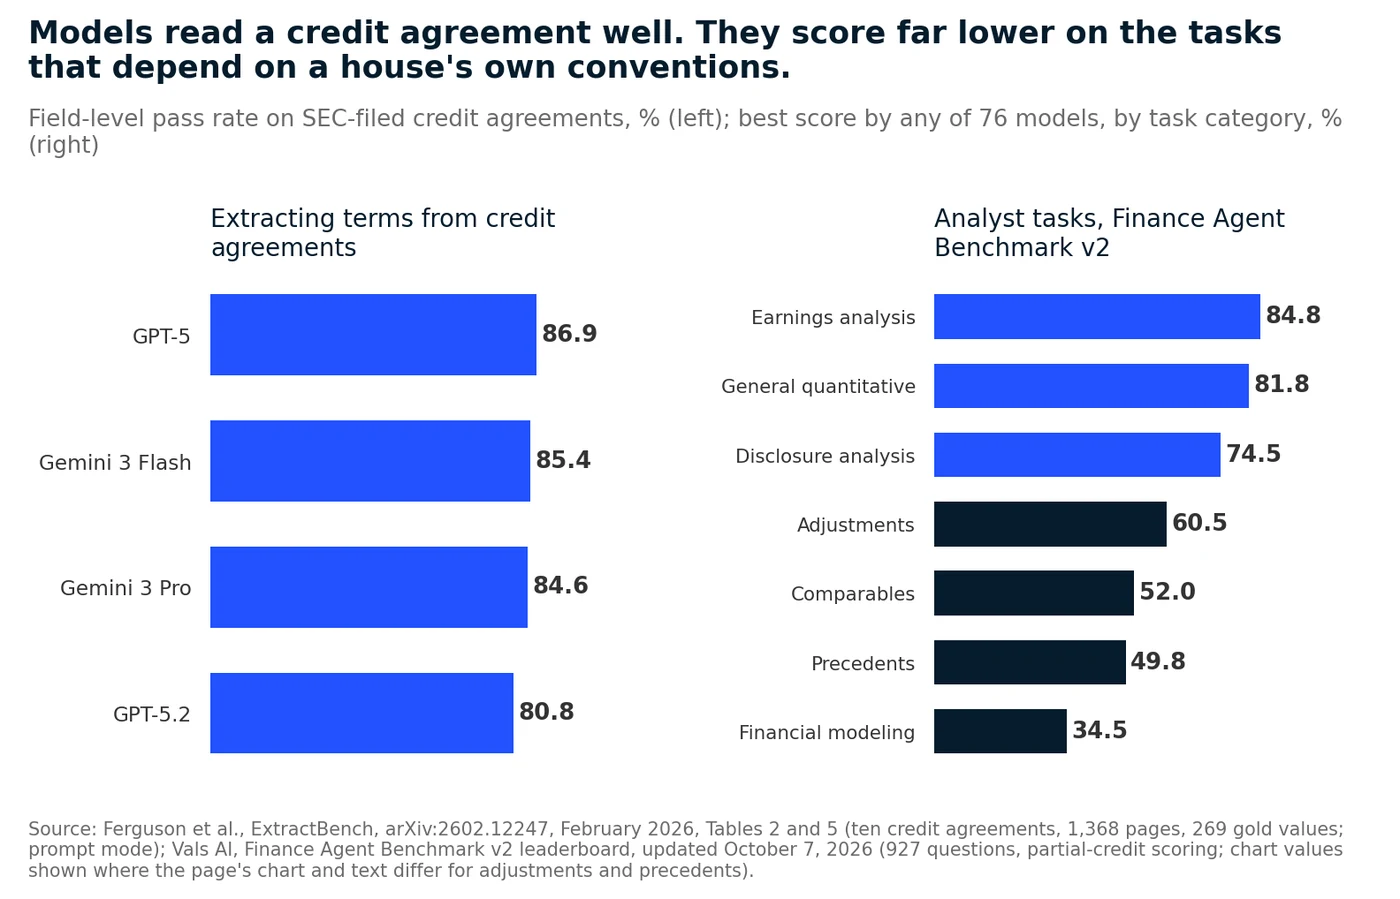
The models of 2026 are good at the part of credit work that is contained in the documents. ExtractBench, published in February, tested frontier models on ten SEC-filed credit agreements of 97 to 218 pages, 1,368 pages in total with 269 gold values. The best models passed 86.9 percent of fields (GPT-5), 85.4 percent (Gemini 3 Flash) and 84.6 percent (Gemini 3 Pro), and credit agreements had the highest pass rate of any dataset despite being the longest documents. (The two Claude models scored zero only because the agreements exceeded a 100-page ingestion limit.)14 Reading a definition of Consolidated EBITDA out of a 200-page agreement is a solved problem.
Applying it the way the house applies it is not. On the Finance Agent Benchmark, updated on October 7 with 927 expert-reviewed questions and 76 models, the best scores are 84.8 percent on earnings analysis (Gemini 4 Argon) and 81.8 percent on general quantitative work. They fall to 60.5 percent on adjustments, 52.0 percent on comparables, 49.8 percent on precedents and 34.5 percent on financial modeling, and no model passes every part of a question more than 51 percent of the time (Exhibit 3).15 Adjustments and precedents are the two categories that describe credit judgment: which add-backs the house accepts, and what the committee decided the last time it saw this fact pattern. They are where the best model in the world is a coin toss.
BigFinanceBench, written by 52 former investment banking and private equity professionals and published in June, locates the failure. The three leading agents, Claude Opus 4.7, GPT-5.5 and Claude Sonnet 4.6, sit within 0.3 points of one another on expert rubrics at 58.8, 58.8 and 58.5 percent, and none exceeds 44.3 percent on final answers. Once a model reaches a clean set-up with the right sources and definitions, calculation scores across nine models span only 3.6 points. The authors write that "many failures accumulate before the final arithmetic stage," at source selection, metric definition and accounting adjustment.16 In credit terms: the model can compute coverage once it knows which EBITDA the house uses, which add-backs it allows, and whether the shareholder loan counts as debt. Those are not facts in the file. They are conventions of the lender, and exactly what a senior credit officer checks, which is why so many credit AI programs report time savings on memo preparation and no change in who decides.
Why the pilots stay in decision support
The industry's own data describe the ceiling. In KPMG's second-quarter pulse of 204 US banking leaders, 39 percent had deployed AI agents and 51 percent were piloting them; the barriers named most often were data readiness and access at 63 percent, the complexity of agentic systems at 49 percent and, third, "human oversight skills" such as human-in-the-loop judgment and escalation at 41 percent. Only 3 percent had assigned accountability for AI decisions to a central governance committee.17 Evident counted 93 new AI use cases announced by 50 global banks in the second quarter, with commercial banking rising from 8 to 22, and found that "only 27% of new use cases carried a disclosed outcome."18
Supervisors have seen the same pattern from the inside. The ECB's workshops with banks using AI in credit risk, summarized in its November 2025 newsletter and cited again by Supervisory Board member Pedro Machado in February, found that none of the 13 banks sampled allows a model to keep learning after deployment, that banks define explainability differently, and that only a few apply data management standards effectively.19 Machado named the governance problem as "fragmented ownership, with responsibility split across IT, data science teams, business lines and control functions," and said a bank that cannot explain a model's output in decision-relevant terms "cannot truly control that model."20 The Bank of England's February roundtables concluded that traditional validation "wouldn't be sustainable in its current form" for generative models and that human-in-the-loop "was also challenged by the rise of agentic AI."21 Vice Chair Bowman's first test of any AI use case, at the FSOC roundtable in April, was whether "its use directly affect[s] consumers and customers, as with credit determinations."22
These are not objections to AI in credit. They describe what the institution must produce before AI can move from drafting the memo to recommending the decision: the definition applied, the exception invoked, the precedent matched, and the person who held the authority. Pilots stop at decision support because that is the most a system can offer when the exception logic exists only in people.
The exception logic is leaving with the people
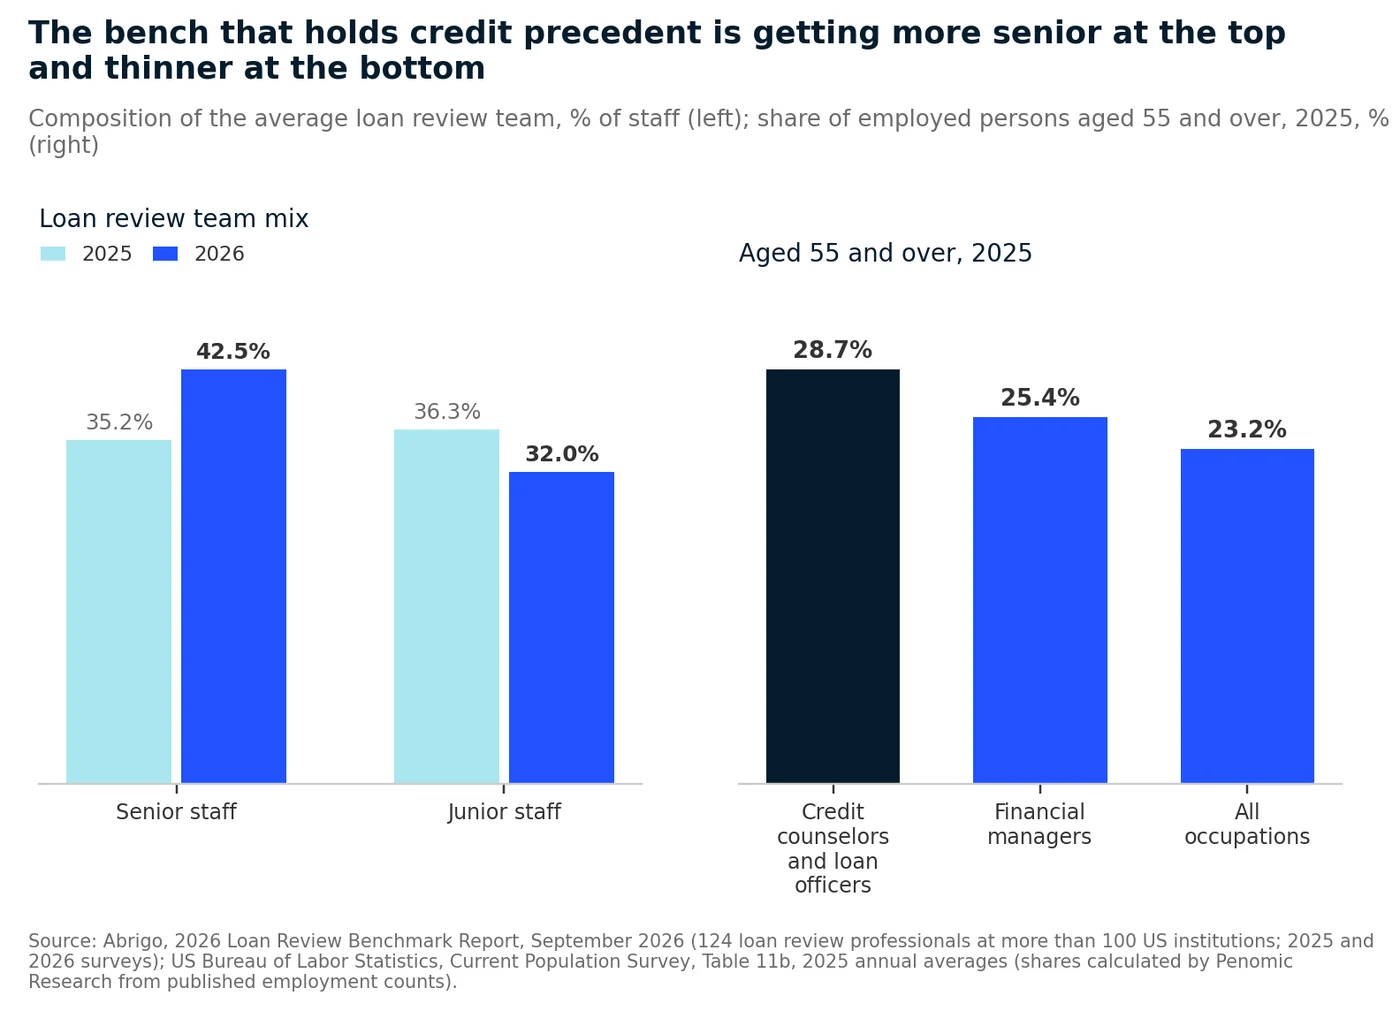
That dependence on people is becoming less safe. In the Bureau of Labor Statistics' 2025 occupational data, 101,000 of the 352,000 employed credit counselors and loan officers were aged 55 or over, 28.7 percent, against 23.2 percent across all occupations; among financial managers the share was 25.4 percent.23 Abrigo's 2026 benchmark of 124 loan review professionals found senior staff rising from 35.2 to 42.5 percent of the average team in a year while junior staff fell from 36.3 to 32.0 percent.24 The bench that holds the precedent is getting more senior and thinner at the bottom at once (Exhibit 4).
Boards know the succession problem and are not solving it. In Bank Director's 2026 compensation survey, 9 percent of banks had identified a CEO successor with a timeline and a plan, down from 17 percent a year earlier, while 69 percent of directors and CEOs said AI expertise was the capability their C-suite most needed.25 In the same firm's risk survey, the share naming credit as a top risk rose to 60 percent from 51 percent, and a third said they did not understand agentic AI at all.26 No survey asks the narrower question: when the chief credit officer and the most senior workout lenders retire, what happens to the exception logic they carry? In our experience it is reconstructed, slowly and imperfectly, from the minutes and memos that were available all along.
There is a structural reason the usual remedy, asking the expert to write the playbook, fails. In a June 2026 study, novices given guidance that experts wrote about their own practice did no better than a baseline, while novices given guidance that a language model had extracted from records of what those experts actually did came close to expert performance.27 The domain was tutoring, not lending, and the finding should be weighted accordingly. But it matches what every head of credit has seen in a policy rewrite: asked to document how they decide, senior lenders describe the standard, and the exception they would make stays in their heads. Precedent has to be mined from the decisions, not dictated in a workshop.
What governed precedent does to a model
The evidence that making institutional conventions explicit changes model behavior comes from the current generation of models, and it is consistent. In an April study, three frontier models were asked 99 analytical questions twice: once with the database schema alone, and once with a short document of business definitions. Without it, Claude Opus 4.7, Claude Sonnet 4.6 and GPT-5.4 scored between 45.5 and 50.5 percent; with it, between 67.7 and 68.7 percent, a gain of 17 to 23 points for each model. The definitions mattered more than the choice of model.28 A July study went further. A model writing queries directly produced at least one hallucination in 79 percent of answers; adding definitions cut that to 40 percent but still leaked row-level access controls on 35 percent of questions; only when definitions were combined with access policy and validation did the hallucination rate reach zero and strict accuracy 79.3 percent.29
Both studies are small, one is vendor-authored, and neither is a loan book. But the structure of the result is the structure of a credit exception. A definition alone (which EBITDA, which add-backs) is a glossary. A definition with the authority attached (who may approve a departure from the leverage ceiling, to what level, with what mitigants, and which cases must go to committee) is a decision a system can apply and a reviewer can trace. The credit knowledge layer is that second object: definitions, exception rules, precedent stored as fact pattern, decision and outcome, and the decision rights that bind them.
What the people shaping the next four years expect
The forecasts worth weighting in credit come from people with a balance sheet, a stability mandate or a supervisory one, and in 2026 they were specific.
- The next downturn will test negotiated outcomes, not models. The IMF's April stability report says selective default rates in direct lending could rise two to three times under stressed rates or earnings, and the FSB's May report calls private credit "untested in a prolonged economic downturn."2 7 The BIS's finding that spreads "may no longer fully account for borrower fundamentals" means the pricing in the file will carry less information, and the lender's own precedent more.6
- The shift to nonbanks will continue, and banks will finance it. Dimon's letter records nonbanks' share of leveraged lending at 64 percent and expects deregulation to free capital "which can be lent out."8 The FDIC's data show where bank lending is going: nondepository financial institutions, up 22.4 percent in a year.9 Lending to a lender requires understanding that lender's exception logic as well as your own.
- Supervisors will ask for the trace. Bowman told the FSOC roundtable that the agencies "should assess whether our supervisory guidance is fit for the future," with credit determinations the first test of whether an AI use directly affects customers.22 Gartner predicts that by 2030, 80 percent of Global 500 companies will contractually make their CIO or chief AI officer the "Evidence Custodian" for AI accountability.30 In credit, the evidence is the definition, the exception and the precedent applied.
- Adoption will outrun the organization. Dimon expects AI deployment may "move faster than workforce adaptation."8 Gartner expects 70 percent of enterprises to abandon agentic AI built for them by vendors' forward-deployed engineers by 2028 because they "fail to build internal capability."31 A credit house that buys its exception logic from a vendor does not have one.
Our own expectation, grounded in those views and in the benchmarks above, is that commercial lending will separate on one variable between now and 2030: whether the house's exception logic and committee precedent exist in a form its systems can apply and its supervisors can inspect. Models will keep converging; the three leaders on BigFinanceBench already sit within a third of a point of one another. The borrowers will keep arriving as exceptions, and the people who hold the precedent will keep retiring. By 2028 we expect the first examination findings to turn on a bank's inability to state which exception rule and which precedent an AI-assisted credit recommendation relied on, and we expect lenders that have structured their exception layer to be the first to move AI from decision support to recommendation on renewals and amendments. By 2030 we expect structured credit precedent to be an inventoried, validated asset at every large commercial lender, governed as a model is governed today.
Building the credit knowledge layer: four moves
The lenders closing this gap are doing four things, in roughly this order.
1. Make the exception the unit of knowledge
Start from the exception log, not the policy manual. For each exception type the bank grants most often (leverage above policy, coverage below policy, covenant waiver, maturity extension, collateral shortfall), write down the conditions under which the house grants it, the mitigants it requires, the authority needed, and the outcomes of the last three years of such exceptions. That inventory is the first version of the credit knowledge layer, and it is what examiners applying SR 26-2 will ask for.
- Concrete marker: Every policy exception granted in the last twelve months is tagged with its type, approving authority, mitigants and current risk rating, and the list reconciles to the exception report the board receives.
- Concrete marker: Each exception type has a named owner in credit risk and a written statement of when the house grants it and when it does not.
2. Mine precedent from the committee, not from the workshop
Committee minutes, approval chains, memo mitigant sections and workout files already contain the house view. Use models to extract the fact patterns, decisions and stated reasons, then have senior lenders confirm or correct what was extracted. The June evidence that behavior-derived guidance beats expert-written guidance says this is the right order; BigFinanceBench's finding that errors begin in definition and adjustment says where to look first.16 27
- Concrete marker: Precedent is stored as fact pattern, decision, reason and outcome, so a new file can be matched to prior cases and the match shown to the approver.
- Concrete marker: Retiring credit officers spend their final two quarters validating extracted precedent, recorded against their name.
3. Attach authority to every definition and exception
Each definition, exception rule and precedent should carry who may apply it, who may depart from it, to what limit, and which cases must return to a person. This is the step the 2026 studies show carries the most weight: definitions alone left 40 percent of answers with a hallucination and leaked access controls; definitions bound to policy and validation did not.29 It is also the step that answers the ECB's charge of fragmented ownership.
- Concrete marker: Every AI-assisted credit output records the definitions, exception rules and precedents it applied and the authority required, so an examiner can trace it without an interview.
- Concrete marker: The cases that must go to committee are specified in advance, and the system cannot route around them.
4. Govern the layer like a model
Credit already has the discipline. Conceptual soundness, independent validation, ongoing monitoring, change control and an inventory with owners are the elements of SR 26-2, which now extends conceptual soundness to qualitative judgments and asks for exceptions to be tracked.13 Applied to the credit knowledge layer, they turn precedent into an asset that survives the retirement of the people who created it and the replacement of the model that reads it.
- Concrete marker: The exception rules and precedent base have an inventory, owners, a review cycle and a change log, and loan review tests AI-assisted recommendations against them.
- Concrete marker: Replacing the underlying language model does not require rebuilding the house's definitions, exception rules or precedent.
The leadership test
No lender has finished this work. Chief credit officers and boards can test their position with six questions:
- What share of the commercial book carries a policy exception, and could we list those exceptions by type, authority and outcome today?
- If a sponsor asked why we approved a structure for one of its companies and declined it for another, would we answer from a record or from memory?
- Which definition of EBITDA, and which add-backs, does our AI memo tool apply, and who decided that?
- When the chief credit officer and the two most senior workout lenders retire, what precedent leaves with them, and what have we done about it this year?
- Could we show an examiner, from the system, which exception rule and which precedent an AI-assisted recommendation relied on?
- If we replaced our language model next year, what part of our credit judgment would we have to rebuild?
Institutions that can answer these questions have a credit knowledge layer. Those that cannot hold their most valuable asset in a form that cannot be inspected, transferred or applied by a system, while the models that read their files get better every quarter at applying the wrong judgment faster.
Commercial credit has always been decided in the exceptions. What has changed in 2026 is that the borrowers have become exceptional as a class, the tools can read every page of every file, and the people who know what the house does with that file are closest to the exit. The lenders that capture the most from AI in credit will not be those with the best model. They will be the ones that wrote down what their committee actually decides, attached the authority to it, and governed it as they govern their models. That is the institution's credit judgment. The work of structuring it has not been done.
Get the PDF
A formatted copy of “Credit decisions live in the exceptions” with every exhibit and source, for reading offline or sharing with your team. We will email you a copy too. You will only be asked once.
Bring one number your institution argues about. In 30 minutes the Penomic Research team maps how each team defines it, who owns each version and where AI would get it wrong. You keep the write-up.
Book a Diagnostic Or request a private architecture briefingNotes
- David Hamilton, "Lend, extend, and then...," Moody's Analytics, May 18, 2026 (Moody's Ratings default data for 2025; soft credit event history 1979 to 2026, 1,173 borrowers; the direct-lending figure is described as a proxy default rate). moodys.com (insight)
- International Monetary Fund, Global Financial Stability Report, April 2026, Chapter 1, section on private credit (selective defaults defined to include amend-and-extend and payment-in-kind options; stressed-scenario estimate of two to three times recent selective default rates). imf.org (chapter PDF)
- Board of Governors of the Federal Reserve System, July 2026 Senior Loan Officer Opinion Survey on Bank Lending Practices, Table 1, questions 1, 2 and 27 (56 domestic banks; survey sent June 17, responses due July 2, 2026). The 26.8 percent figure combines banks that eased spreads somewhat (25.0 percent) and considerably (1.8 percent). federalreserve.gov/data/sloos/sloos-202607.htm; Table 1 (PDF)
- Cambridge Centre for Alternative Finance, The 2026 Global AI in Financial Services Report, April 2026 (n=628 across 151 jurisdictions; industry n=352, regulators n=130; fieldwork October 2025 to January 2026). jbs.cam.ac.uk (report PDF)
- Bank Director, 2026 Technology Survey, sponsored by Jack Henry, September 2026 (136 directors, CEOs, COOs and senior technology executives at US banks under $100 billion in assets; fieldwork June to July 2026). Lending shares are of banks that have implemented each form of AI. bankdirector.com (report PDF)
- Puriya Abbassi, Iñaki Aldasoro and Sebastian Doerr, "Financing the digital economy: the role of private credit," BIS Quarterly Review, September 14, 2026, including Box A on borrower and loan characteristics, 2010 to 2025. bis.org (article)
- Financial Stability Board, Report on Vulnerabilities in Private Credit, May 6, 2026 (market size estimate of $1.5 trillion to $2.0 trillion at end-2024; bank credit lines to private credit funds of about $220 billion in reported data). fsb.org (press release)
- Jamie Dimon, Chairman and CEO letter to shareholders, JPMorganChase 2025 Annual Report, April 6, 2026, including the comparison tables for 2010 and 2025. jpmorganchase.com/ir/annual-report/2025/ar-ceo-letters
- Federal Deposit Insurance Corporation, Quarterly Banking Profile, Second Quarter 2026, released August 25, 2026 (4,238 insured institutions; loan growth, past-due and nonaccrual rates, and Table V-A noncurrent rates by loan category). fdic.gov (QBP PDF)
- Board of Governors of the Federal Reserve System, FDIC and OCC, Shared National Credit Program: 1st and 3rd Quarter 2025 Reviews, January 12, 2026 (total commitments $6,911.4 billion; special mention plus classified $592.9 billion; "Other Investors" $1,485.7 billion of commitments and $359.9 billion of special mention and classified). federalreserve.gov (report PDF)
- Office of the Comptroller of the Currency, Semiannual Risk Perspective from the National Risk Committee, Spring 2026, May 7, 2026. The OCC site blocks automated retrieval; the report's credit findings were confirmed through published summaries by Young & Associates and Compliance Cohort (May 2026). occ.gov (report PDF)
- OCC Bulletin 2026-33, "Allowances for Credit Losses: Revised Comptroller's Handbook Booklet and Rescissions," July 16, 2026; examiner-expectation detail and quotations from ICBA, Independent Banker, "Examiner-Ready CECL: What the OCC's 2026 Handbook Update Changes," September 1, 2026 (sponsored content). occ.gov (bulletin); independentbanker.org (article)
- Board of Governors of the Federal Reserve System, OCC and FDIC, SR 26-2, Revised Guidance on Model Risk Management, April 17, 2026 (supersedes SR 11-7 and SR 21-8), Section V on conceptual soundness and the documentation provisions; footnote 3 excludes generative and agentic AI from scope. federalreserve.gov (guidance PDF)
- N. Ferguson, J. Pennington, N. Beghian, A. Mohan, D. Kiela, S. Agrawal and T. H. Nguyen, ExtractBench: A Benchmark and Evaluation Methodology for Complex Structured Extraction, arXiv:2602.12247v2, February 13, 2026, Tables 2, 5 and 10 (credit agreements: 10 documents, 1,368 pages, 269 gold values; prompt mode; models as of February 2026). arxiv.org/abs/2602.12247
- Vals AI, Finance Agent Benchmark v2 leaderboard, updated October 7, 2026 (927 expert-reviewed questions, nine categories, 76 models; partial-credit scoring; category leaders as shown in the benchmark chart). The page's chart and text differ for adjustments (60.5 versus 56.3) and precedents (49.8 versus 36.4); chart values are cited. vals.ai/benchmarks/fabv2
- Wang, Meinhardt, Katz, Kim, Blagden et al., BigFinanceBench: A Workflow-Grounded Benchmark for Financial-Research Agents, arXiv:2606.03829, June 2, 2026, Table 3 and conclusion (928 items, 52 subject-matter experts, 12 reviewers). arxiv.org/abs/2606.03829
- KPMG, AI Quarterly Pulse Survey, Q2 2026: Banking, June 2026 (n=204 US leaders at organizations with revenue above $1 billion; fieldwork April 28 to May 25, 2026). kpmg.com (survey PDF)
- Evident Insights, Q2 2026 Banking AI Use Case Trends Report, 2026 (50 banks in the Evident AI Index; 93 new use cases announced in the second quarter of 2026). The page carries no publication date. evidentinsights.com (report page)
- ECB Banking Supervision, "AI's impact on banking: use cases for credit scoring and fraud detection," Supervision Newsletter, November 20, 2025 (workshops with 13 banks; annual data collection covering 110 significant institutions in 2024). A late-2025 source used because the February 2026 speech cited in note 20 refers to it and no 2026 equivalent has been published. bankingsupervision.europa.eu (newsletter)
- Pedro Machado, "Technology is neutral, governance is not: AI adoption in the banking sector," speech, ECB Banking Supervision, Frankfurt, February 24, 2026. bankingsupervision.europa.eu (speech)
- Bank of England, Summary of AI roundtables, February 2026, February 16, 2026 (roundtables held in late 2025). bankofengland.co.uk/minutes/2026/february/summary-of-ai-roundtables-feb-2026
- Michelle W. Bowman, "Artificial intelligence in the financial system," remarks at the FSOC Artificial Intelligence Series Roundtable, April 27, 2026 (published May 1, 2026). federalreserve.gov (speech PDF)
- US Bureau of Labor Statistics, Current Population Survey, Table 11b, "Employed persons by detailed occupation and age," 2025 annual averages (credit counselors and loan officers: 352,000 employed, 85,000 aged 55 to 64 and 16,000 aged 65 and over; financial managers: 1,431,000, 293,000 and 71,000; all occupations: 163,493,000, 26,605,000 and 11,374,000). Shares are Penomic calculations from these counts. bls.gov/cps/cpsaat11b.htm
- Abrigo, 2026 Loan Review Benchmark Report, September 2026 (124 loan review professionals at more than 100 US institutions from about $500 million to more than $100 billion in assets; team composition compared with the 2025 survey). abrigo.com (report page)
- Bank Director, 2026 Compensation & Talent Survey, sponsored by Chartwell Partners, June 16, 2026. bankdirector.com (article)
- Bank Director, 2026 Risk Survey, sponsored by Baker Tilly, press release, March 31, 2026. prnewswire.com (release)
- M. Cho, R. J. Funk, A. Gupta and M. Yang, Large Language Models Explain Experts Better Than Experts Themselves, arXiv:2608.07488, June 14, 2026 (math tutoring; Study 2 n=456 novices across five conditions; GPT-4o pipeline replicated with Claude Haiku 4.5 and Sonnet 4.5). arxiv.org/abs/2608.07488
- M. Rumiantsau and I. Fokeev, Semantic Layers for Reliable LLM-Powered Data Analytics: A Paired Benchmark of Accuracy and Hallucination Across Three Frontier Models, arXiv:2604.25149, April 28, 2026, Table 1 (99 questions, one of 100 excluded for a memory quota; every cross-cluster comparison significant at p below 0.01). The authors work for Cube, a semantic-layer vendor. arxiv.org/abs/2604.25149
- A. Sasidharan Pillai, GROUND: Reducing Hallucinations in LLM-Based Enterprise Analytics Through Governed Semantic Definitions, arXiv:2608.26157, July 6, 2026, Section 8.1 (100 questions; claude-opus-4-8; adversarial set replicated across four models from three providers). arxiv.org/abs/2608.26157
- Gartner, "Gartner Unveils Top Strategic Predictions for 2027 and Beyond," press release, September 15, 2026. gartner.com (September 15, 2026 release)
- Gartner, "Gartner predicts 70 percent of enterprises will abandon agentic AI built by vendor forward-deployed engineering by 2028," press release, September 29, 2026. gartner.com (September 29, 2026 release)
Copyright © 2026 Penomic. All rights reserved. Exhibits are drawn by Penomic Research from the data published in the sources cited; no third-party figures are reproduced. Benchmark results are reported as published and reflect model versions available at the dates shown.
More from Penomic Research
The institutional intelligence gap
Financial institutions have wired AI into their data. Value stalls because the firm's definitions, policy, precedent and judgment were never made machine-usable.
Why AI pilots stall after the demo
2026 surveys, bank disclosures and agent benchmarks show that AI pilots stall because the institution's definitions, precedent and decision rights were never written down and governed.
Govern the agent through the institution's decision rights
2026 adoption data, agent benchmarks, misalignment studies and supervisory statements show why agent control belongs in the institution's decision rights, not the model's prompt.